
Knowledge
AI pipelines and the idea behind data science
An AI pipeline is a fixed series of steps. AI reads, software calculates, people decide. This is how you build one you can trust.
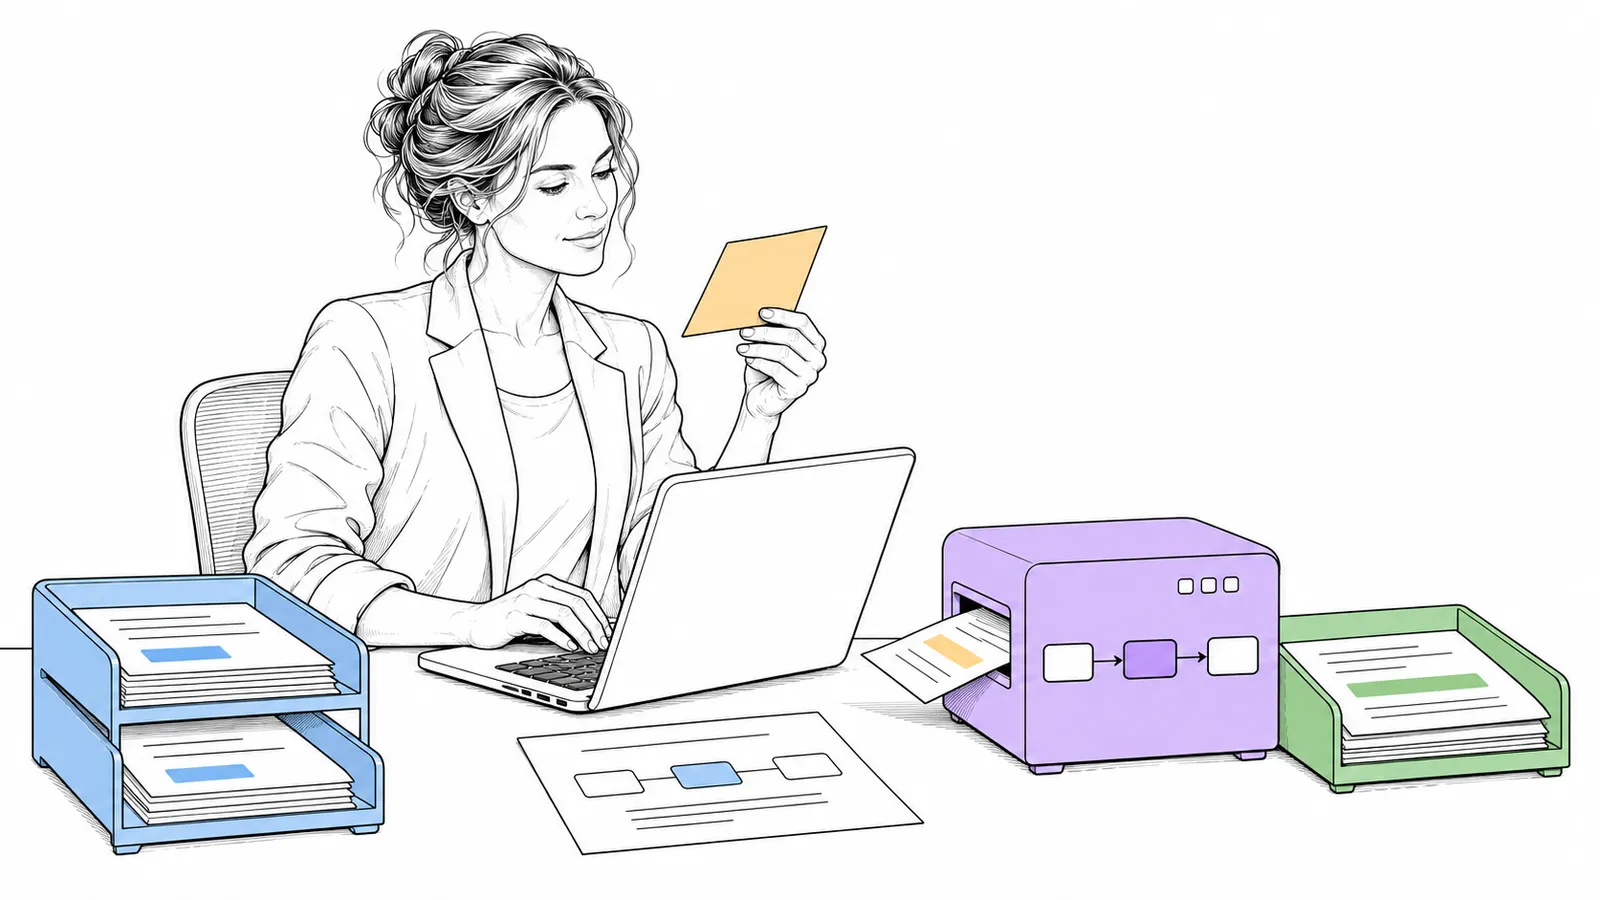
An AI pipeline is a fixed series of steps that data goes through: fetch, clean, extract, check, store, show. AI does one or two of those steps, not all of them.
Plain technical English A pipeline is a fixed order of steps with data as input. A language model reads text and turns it into fields. Rules and code check the fields, and a person decides when in doubt.
Why it matters
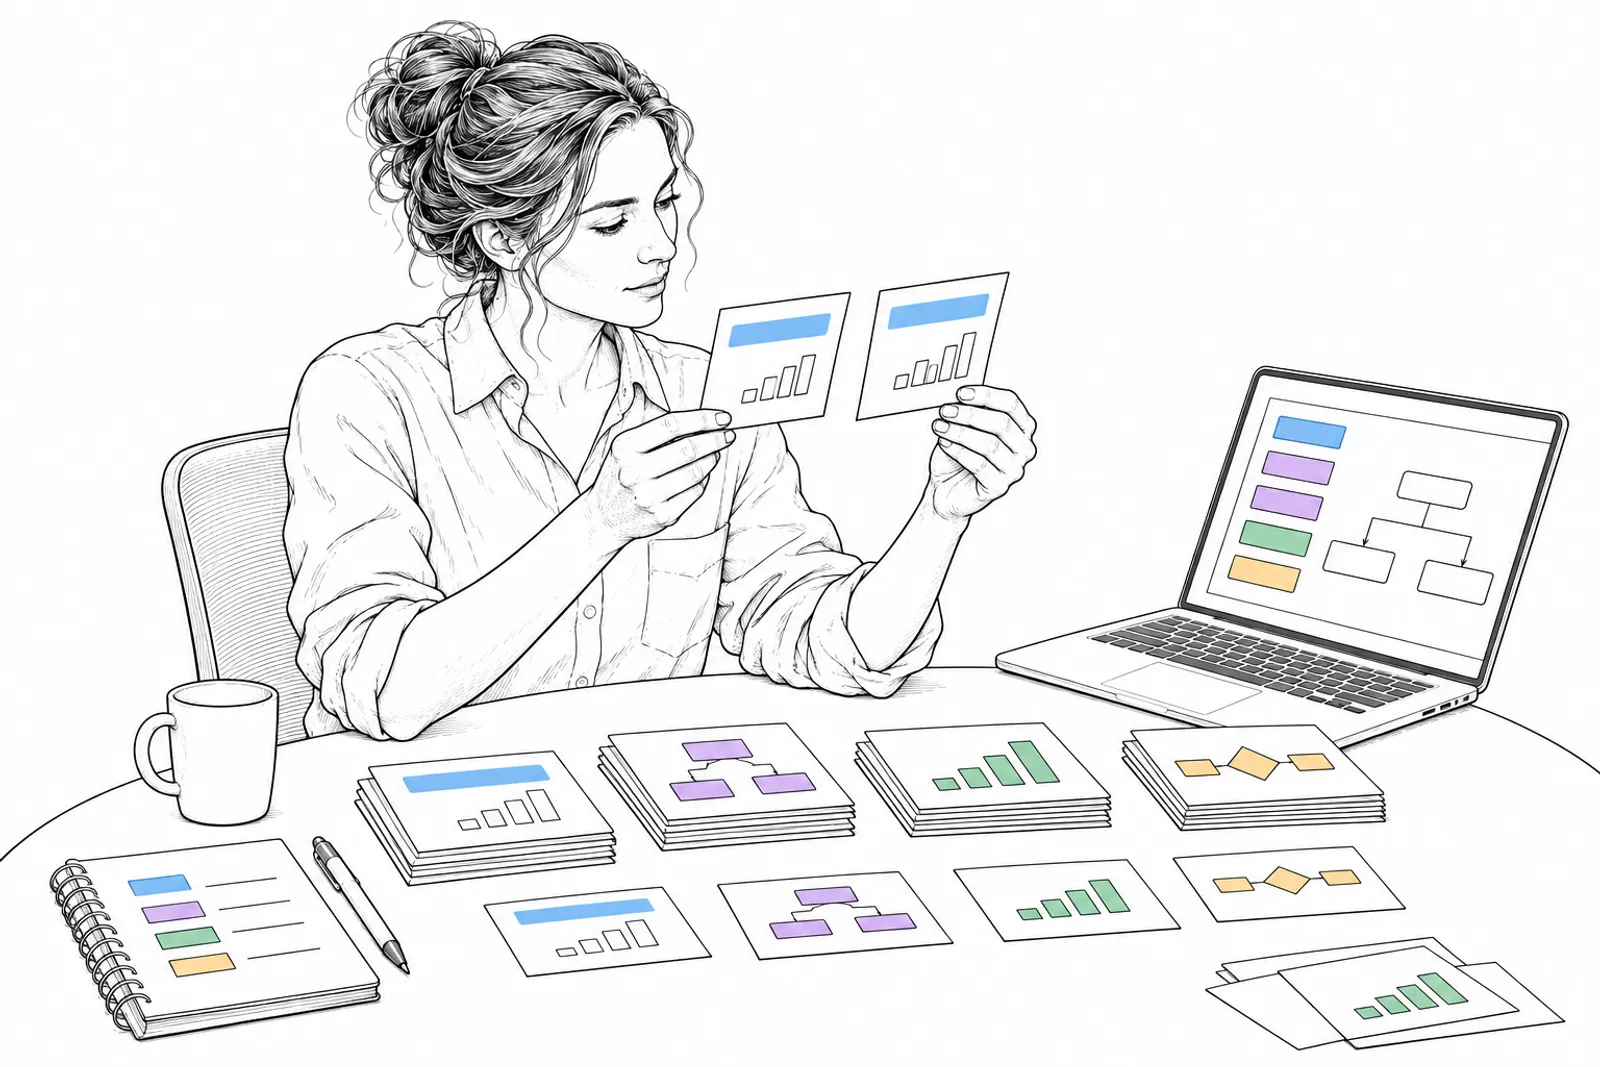
Data science is the field that uses statistics, code and method to get knowledge out of messy data. Most of that work is not the model, but understanding the data. Andrej Karpathy writes in his recipe: the first step is no code, but become one with the data. That is how he found duplicate examples and wrong labels.
If you leave everything to a language model, you get a slightly different answer every time. For an invoice or a stock count, you want it right, every time. So: AI reads, software calculates, people decide.
How it works
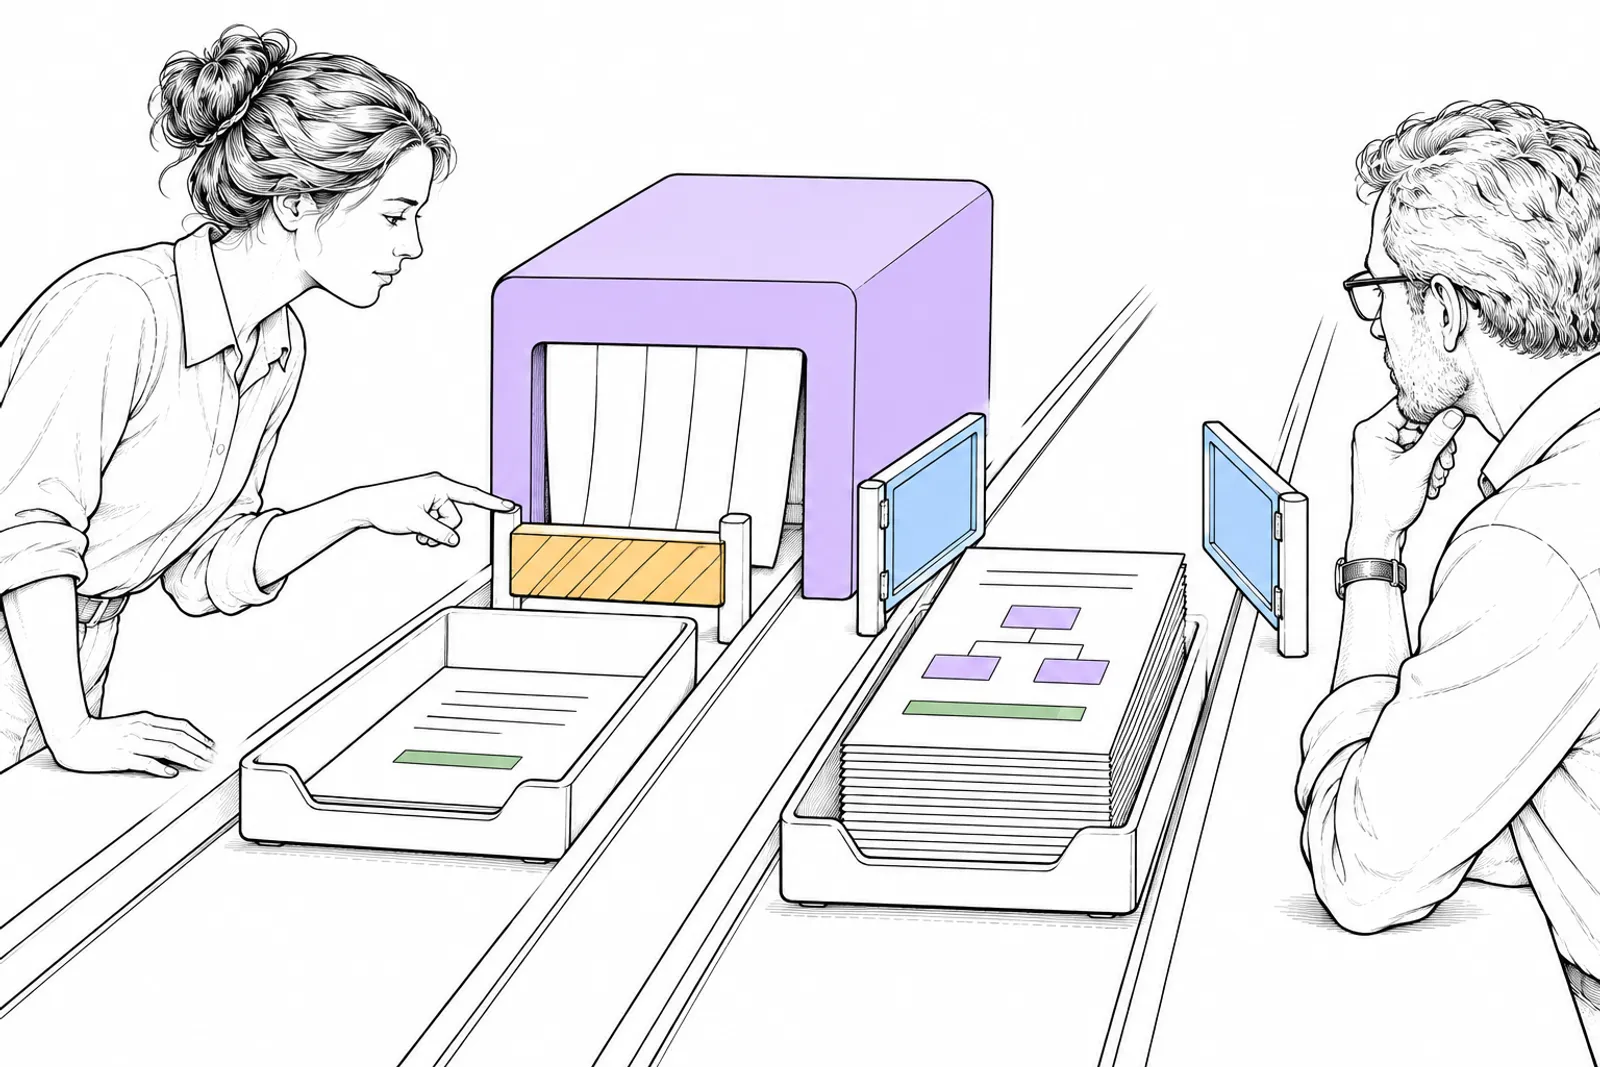
A cheap check before the model, rules after it, and a person when in doubt.
From an earlier project we studied, a real-time assistant for customer service, we took four lessons:
- Check before you generate. Too little input? Then no model call, but a fixed text. That saves money and mistakes.
- Facts from rules, language from the model. A rule decides that a warning is needed; the model only turns it into a readable sentence.
- Every step testable on its own, with a mock of the external systems.
- Logs with ids only, no personal data.
What you do
- First look yourself at a hundred real examples of your data.
- Draw the steps. Mark each step: AI, code or person.
- Build the whole line with simple steps first, then improve step by step.
- Measure per step how often it is right.
An example from our own work: for a search engine, we compared a fixed scraping pipeline with an agent that searched by itself. The pipeline took 32 minutes and found 49 providers. The agent took 10 minutes and found 53.
What we can do with you: together we draw your data flow and build the pipeline, with AI only where it helps. Book a conversation.